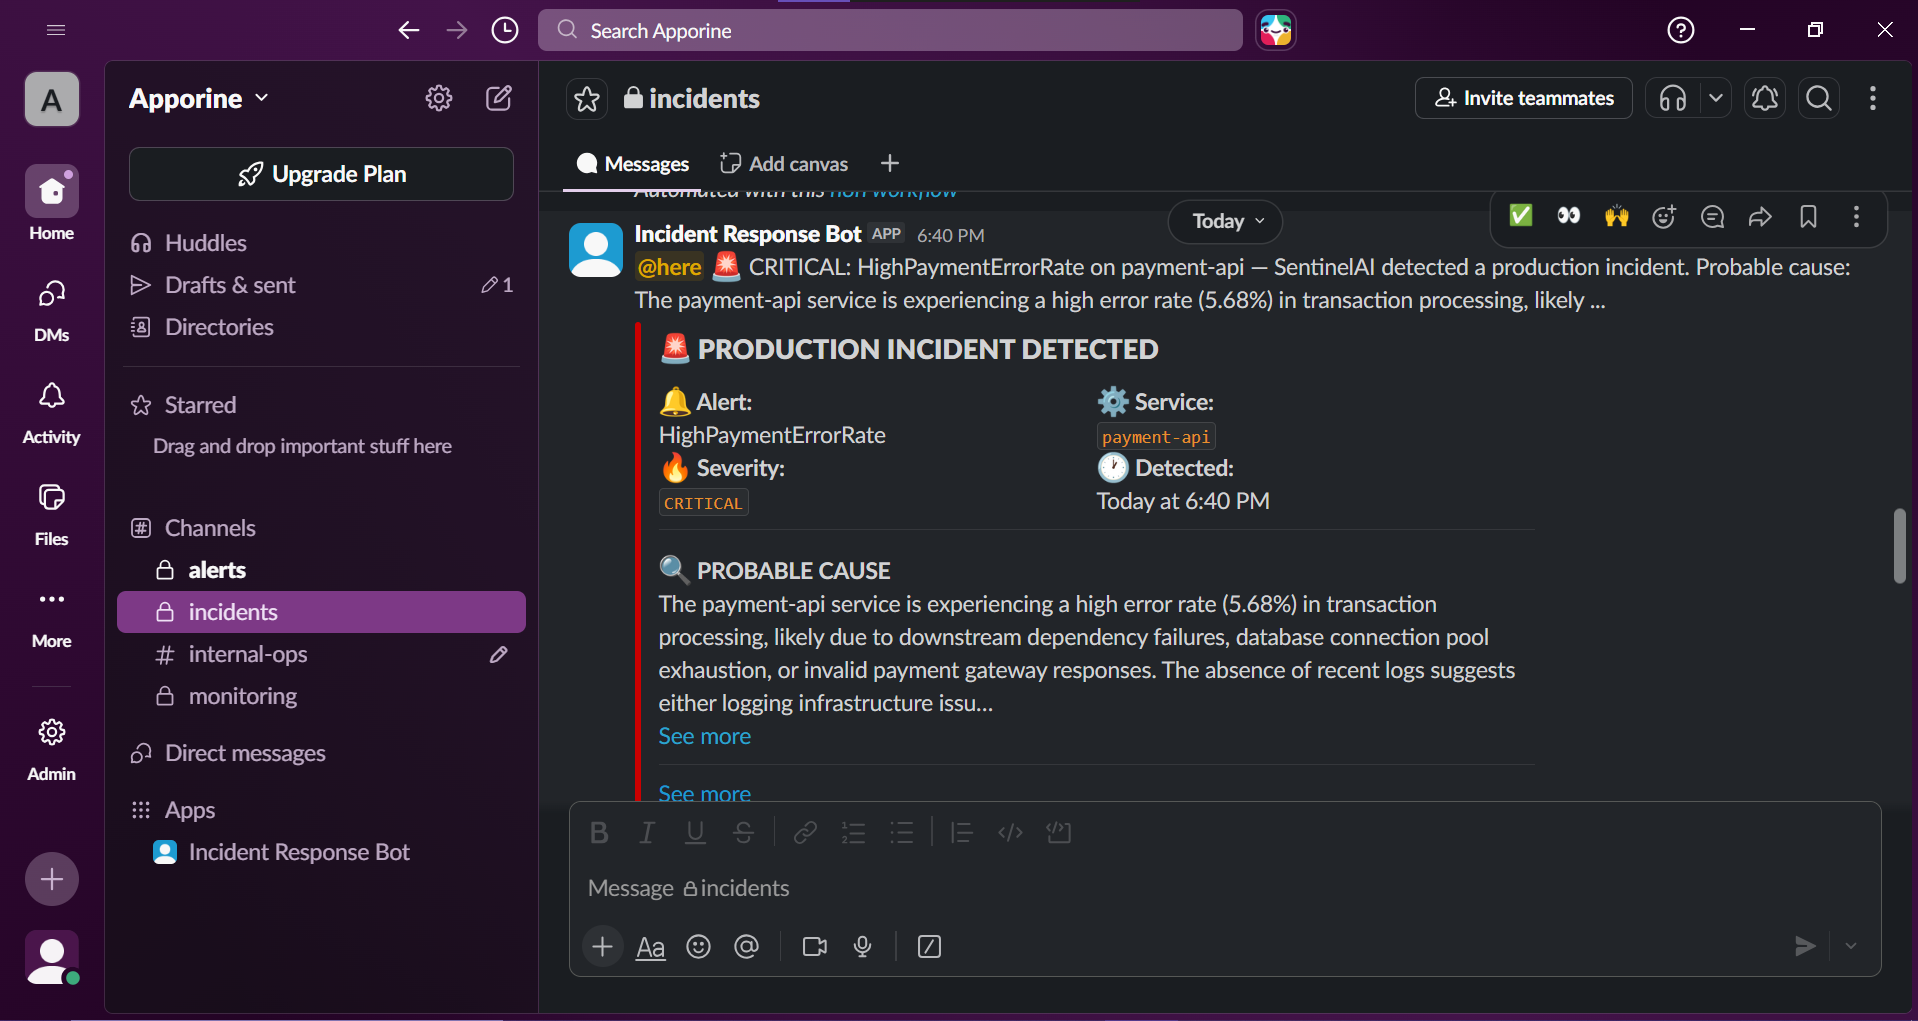
From four-hour firefighting to 23-second detection.
SentinelAI turns production alerts into structured diagnosis, escalation and remediation, with audit trails instead of tribal knowledge.

I design and stabilise the systems behind growing products, deployment pipelines, observability, cloud infrastructure and automation, so teams can ship with confidence instead of firefighting.
Real portfolio screens, shown as a short motion reel. Incident diagnosis, observability and ownership stay connected instead of becoming separate screenshots.
Every case starts with the same question: what was breaking, what changed, and what measurable evidence says the system is better now?
SentinelAI turns production alerts into structured diagnosis, escalation and remediation, with audit trails instead of tribal knowledge.

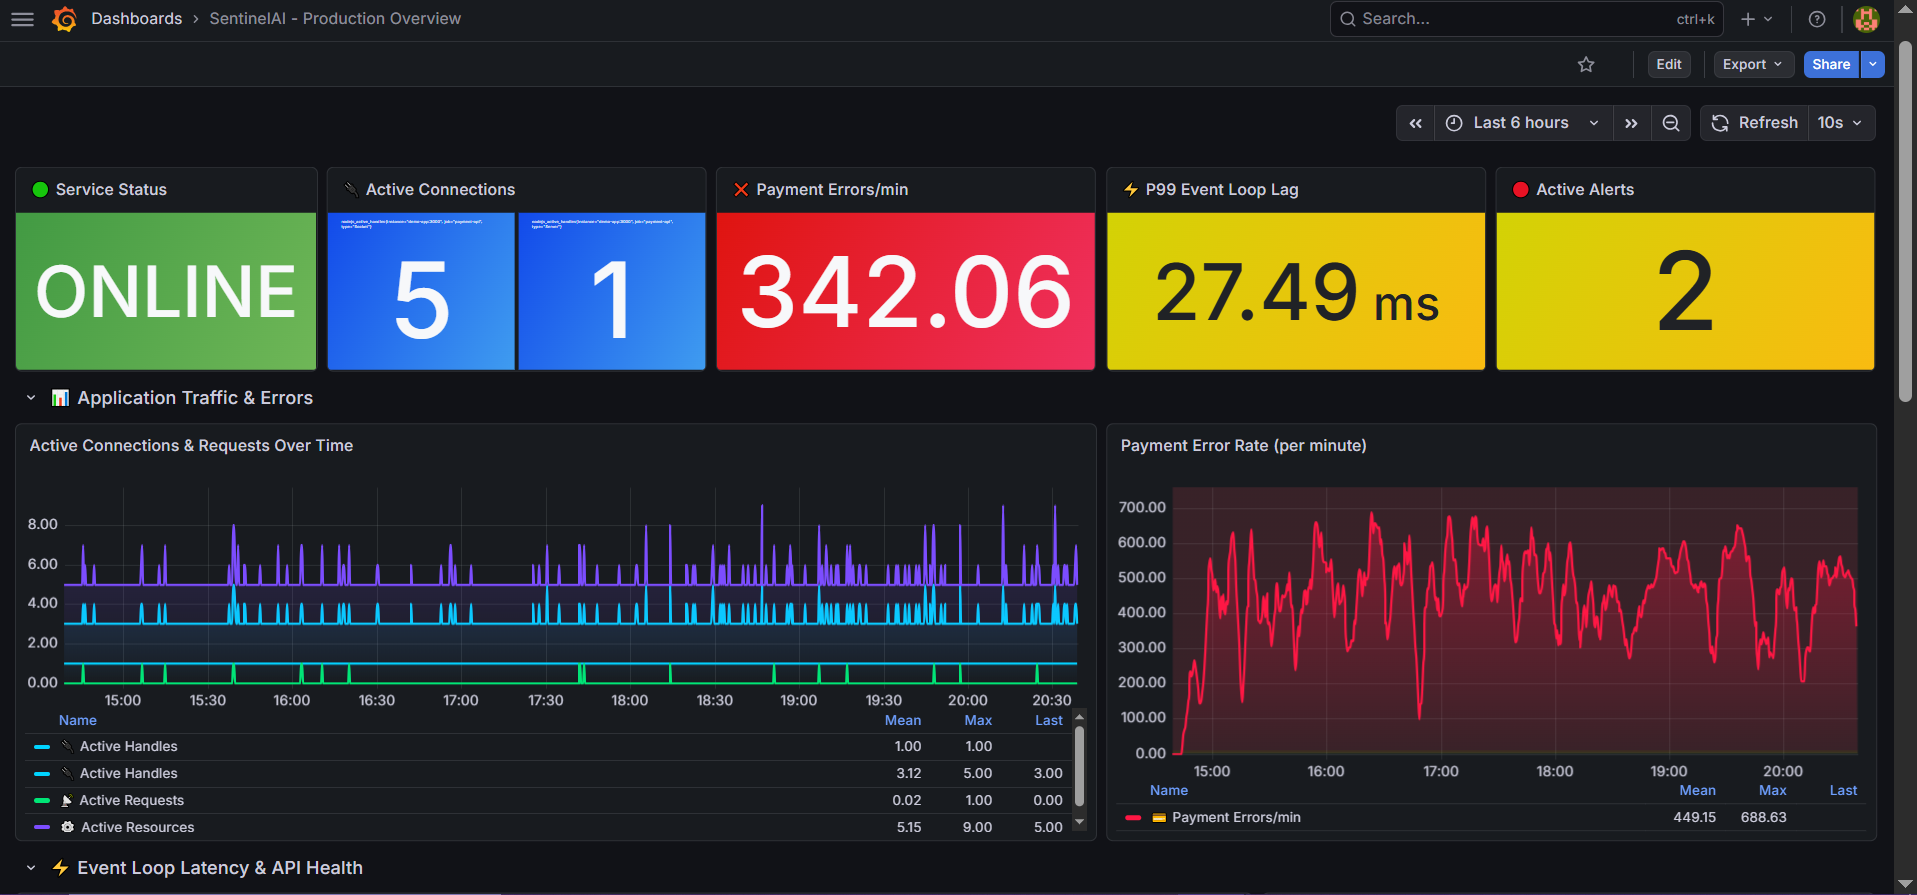
A production observability layer built around real service health, actionable alerts and dashboards that answer operational questions quickly.

Recurring operational work mapped, connected and automated across business tools so the team stops paying an engineering tax every week.
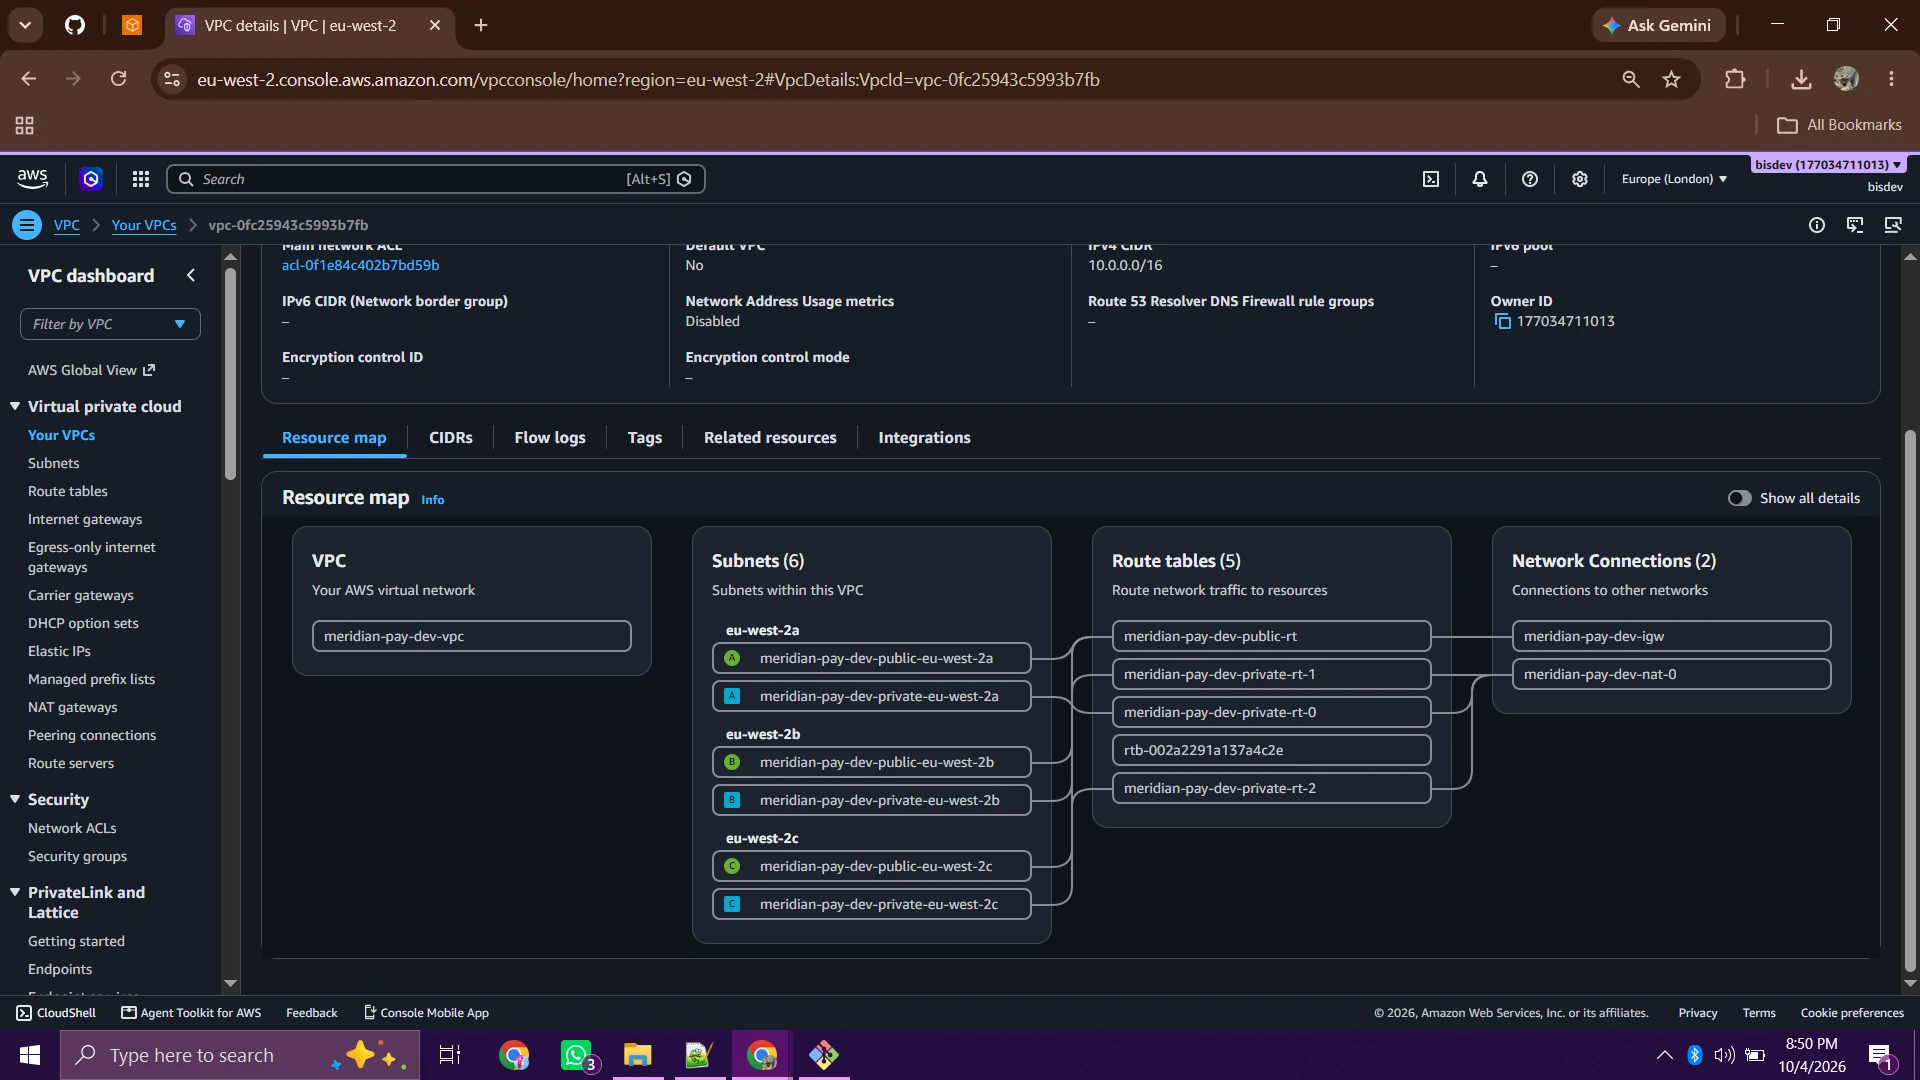
Meridian Pay brings infrastructure, delivery, isolation and operational evidence together across eight services and three network-isolated trust zones.

I am most useful when the problem crosses boundaries: application delivery, infrastructure, visibility and operational automation.
Make releases predictable, recoverable and boring, even when traffic and teams grow.
Make system health visible before customers become the alerting layer.
Remove repeated operational work with workflows that are auditable, owned and maintainable.
The tools change. The standards should not.
Shipping faster is only useful when rollback, recovery and blast radius are understood.
Measure what the system is doing before making it faster, cheaper or more automated.
The system should still make sense after I leave. Handover is part of the build, not an afterthought.
No black-box delivery and no artificially long retainers. We choose the smallest engagement that can solve the real production problem.
We map the system, the failure modes, ownership and the evidence that matters.
Scope, architecture, risks, milestones and success criteria are written before build starts.
You see progress, trade-offs and decisions as the system takes shape.
Documentation, runbooks and knowledge transfer are part of done.
A practical stack across cloud, delivery, observability, automation and application development.
My job is not to make a system look impressive in a demo. It is to reduce uncertainty when the system is live, people are depending on it, and the next engineer needs to understand what happened.
Feedback from teams that brought me into real production problems, focused on outcomes, communication and what changed after delivery.
“Bisma didn’t just set up our CI/CD pipeline, she rewrote how we think about deployments. We went from dreading Fridays to shipping twice a day without a second thought.”
“I was skeptical about the timezone difference. I shouldn’t have been. Bisma responded faster than my local contractors and caught a critical database issue before any client noticed.”
“The automation work reclaimed 15 hours a week for my team. She spotted three workflows I hadn’t thought about and automated those too. Recommended without reservation.”
“Working with Bisma felt like having a senior DevOps engineer on our team full time. She flagged risks we hadn’t seen and delivered ahead of schedule. We’ve rehired her twice.”
“Our cloud bill dropped 38% in the first month. Bisma identified waste we didn’t know existed. Clear communication throughout, we always knew exactly what was happening.”
Both. Most work is scoped around a concrete production outcome. For longer operating needs, I can work as an embedded specialist or on a retainer.
That is a good starting point. We begin with the failure mode, operational cost and constraints, then choose the smallest useful intervention.
Yes. I can own a defined workstream or plug into an existing team, tools and delivery process.
I work remotely with planned overlap across UK, US and Australian working hours, depending on the engagement.
Send the context. I’ll tell you where I think the risk is, what I would investigate first, and whether I am the right person to help.