Production case files

Work that has to survive production.

Selected engagements documented by the problem, constraints, decisions and measurable outcome, not by polished mockups alone.

50+Projects delivered
5+Capability areas
100%Job success
OpenFor select work
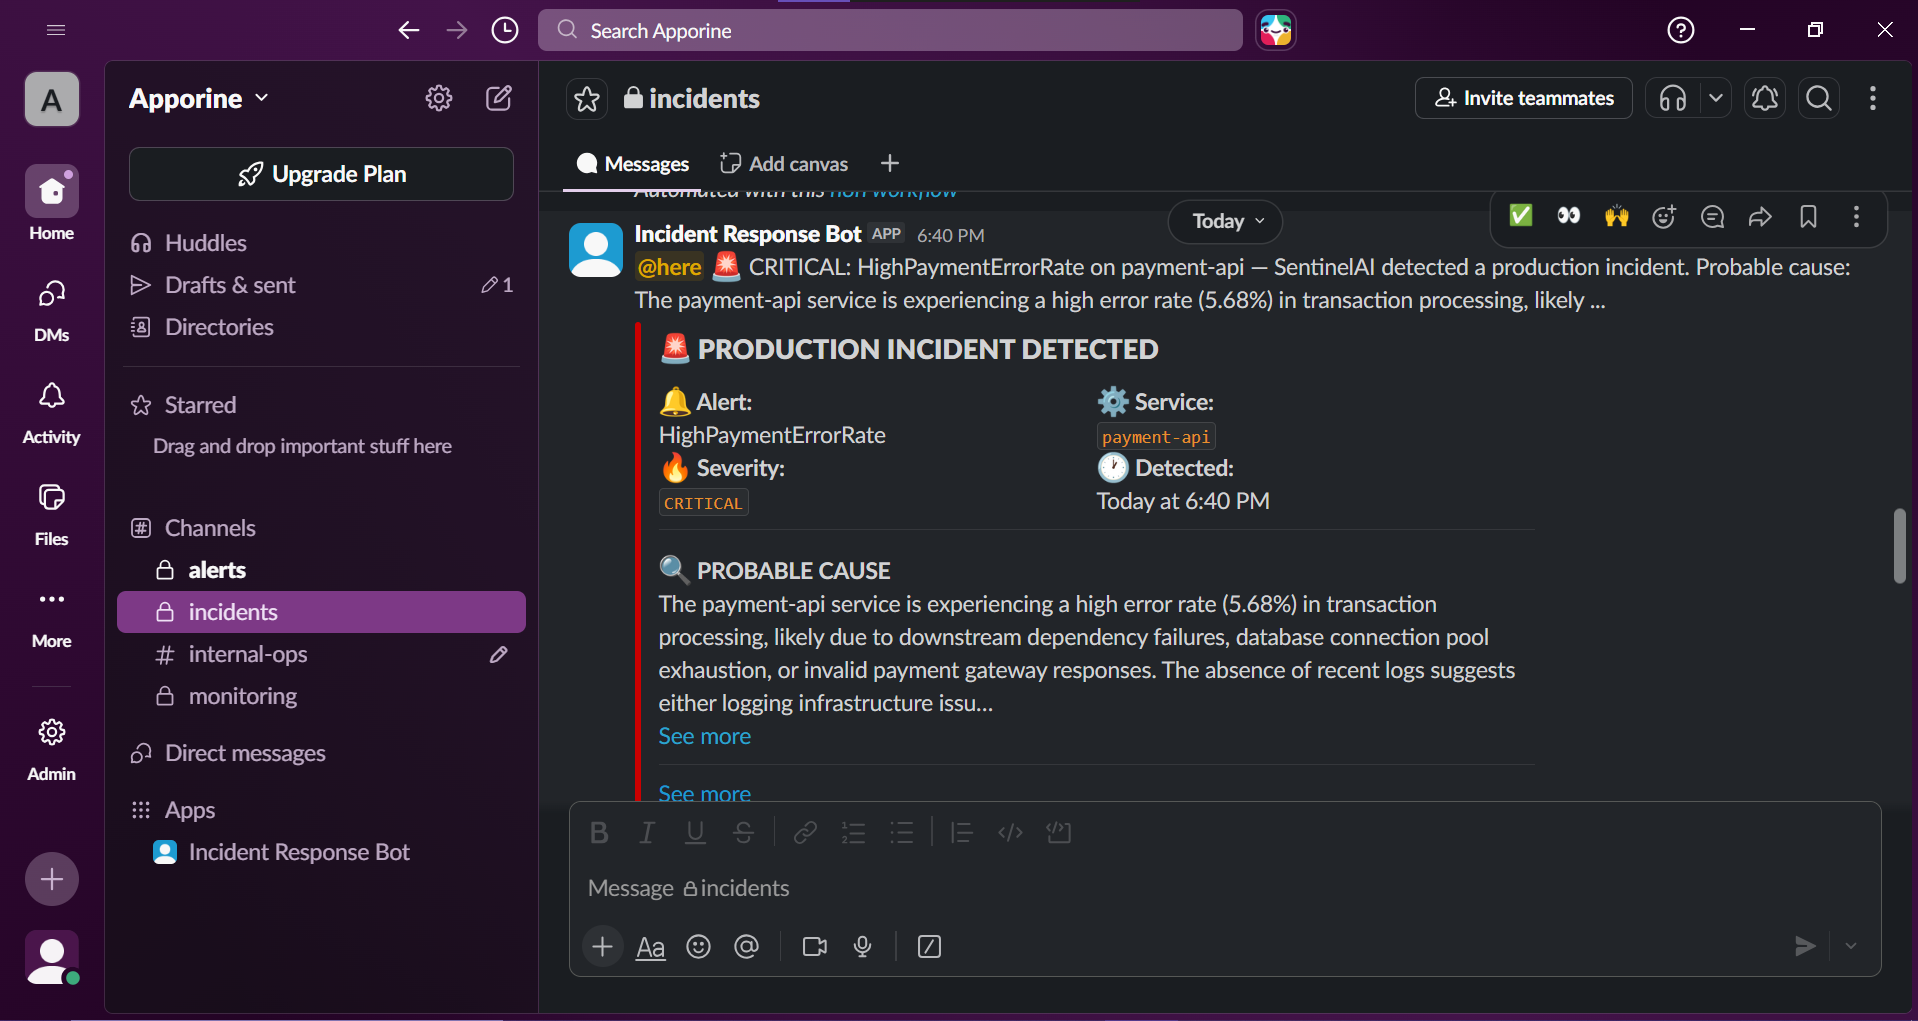
SentinelAI incident response notification
Incident responseProduction automation

From four-hour firefighting to 23-second detection

An AI-assisted incident-response workflow that detects, diagnoses, escalates and documents production incidents with a clear audit trail.

67% auto-resolvedMTTR 14 min99.9% uptime
Prometheus · Grafana · n8n · Claude AIFull case study ↗
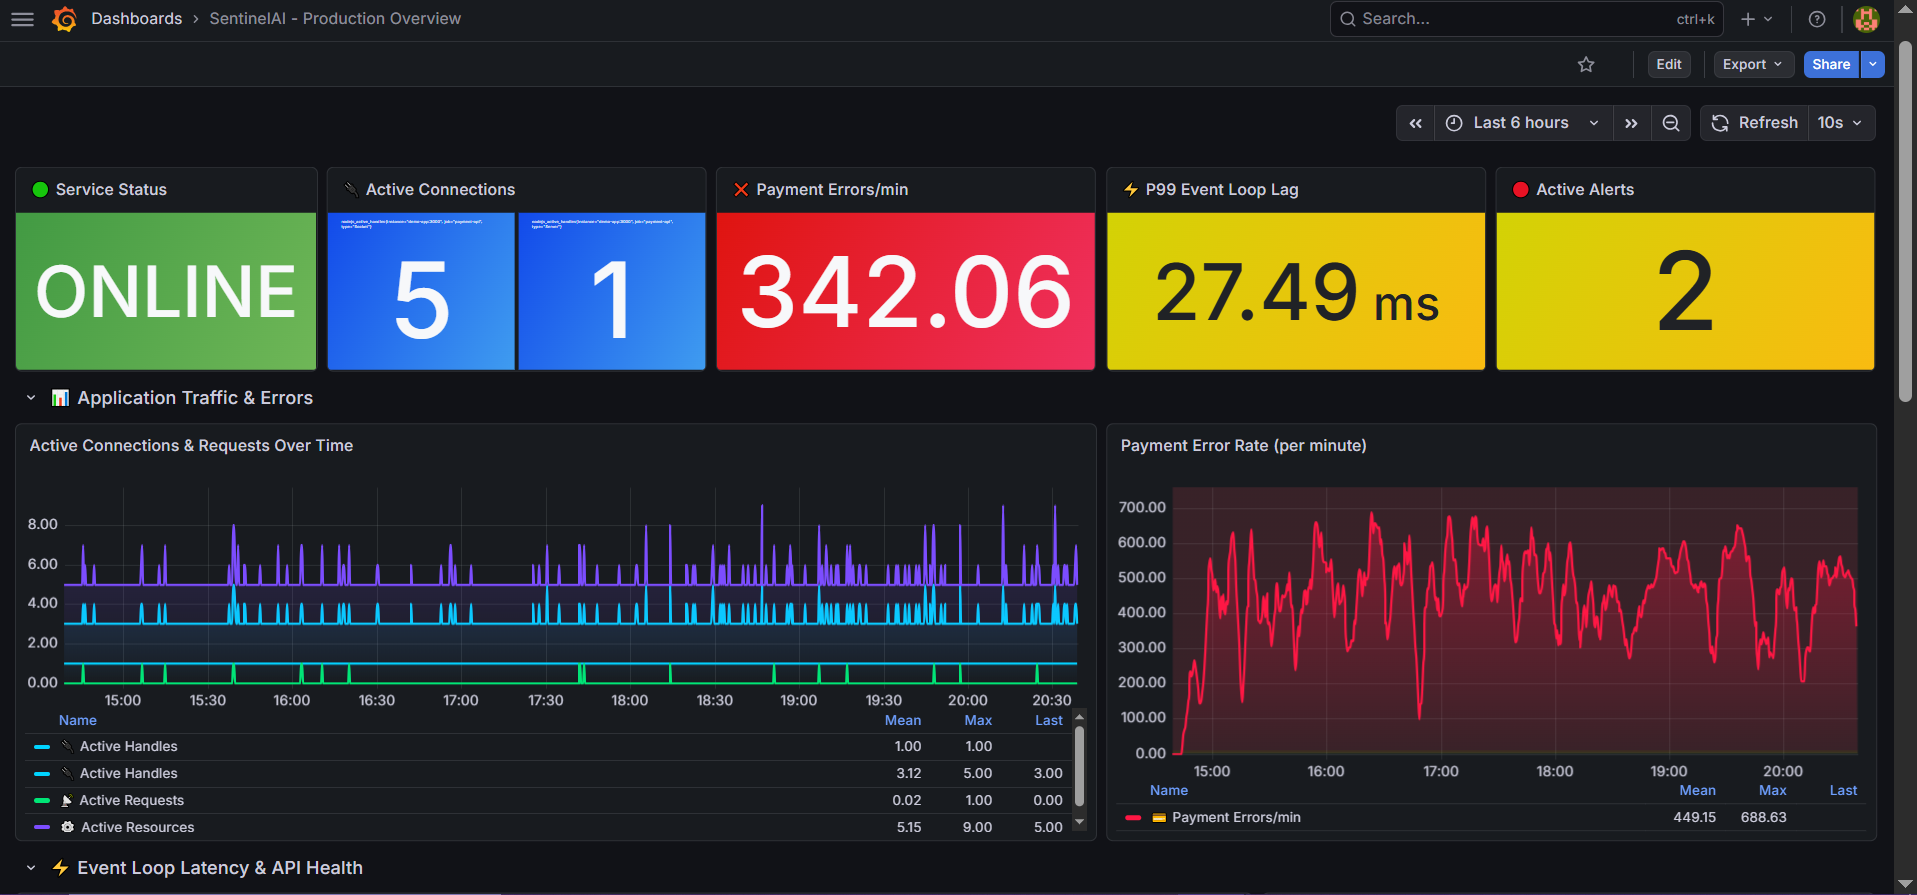
Grafana observability dashboard
Observability

From blind failures to real-time production visibility

Dashboards, alerts and operational views designed around the questions engineers need answered during an incident.

12 dashboards60% faster response40 min earlier detection
Grafana · Prometheus · Loki · AlertmanagerDiscuss a similar system ↗
Workflow orchestration / operating map
CRM
n8n
Slack
Reports
23 workflows running
Automation

Manual operations turned into 23 running workflows

Recurring operational work was mapped, connected and automated across CRM, invoicing, communication and reporting tools.

15 hrs/week reclaimed23 workflowsAPI-led
n8n · Make · REST APIs · WebhooksDiscuss automation ↗
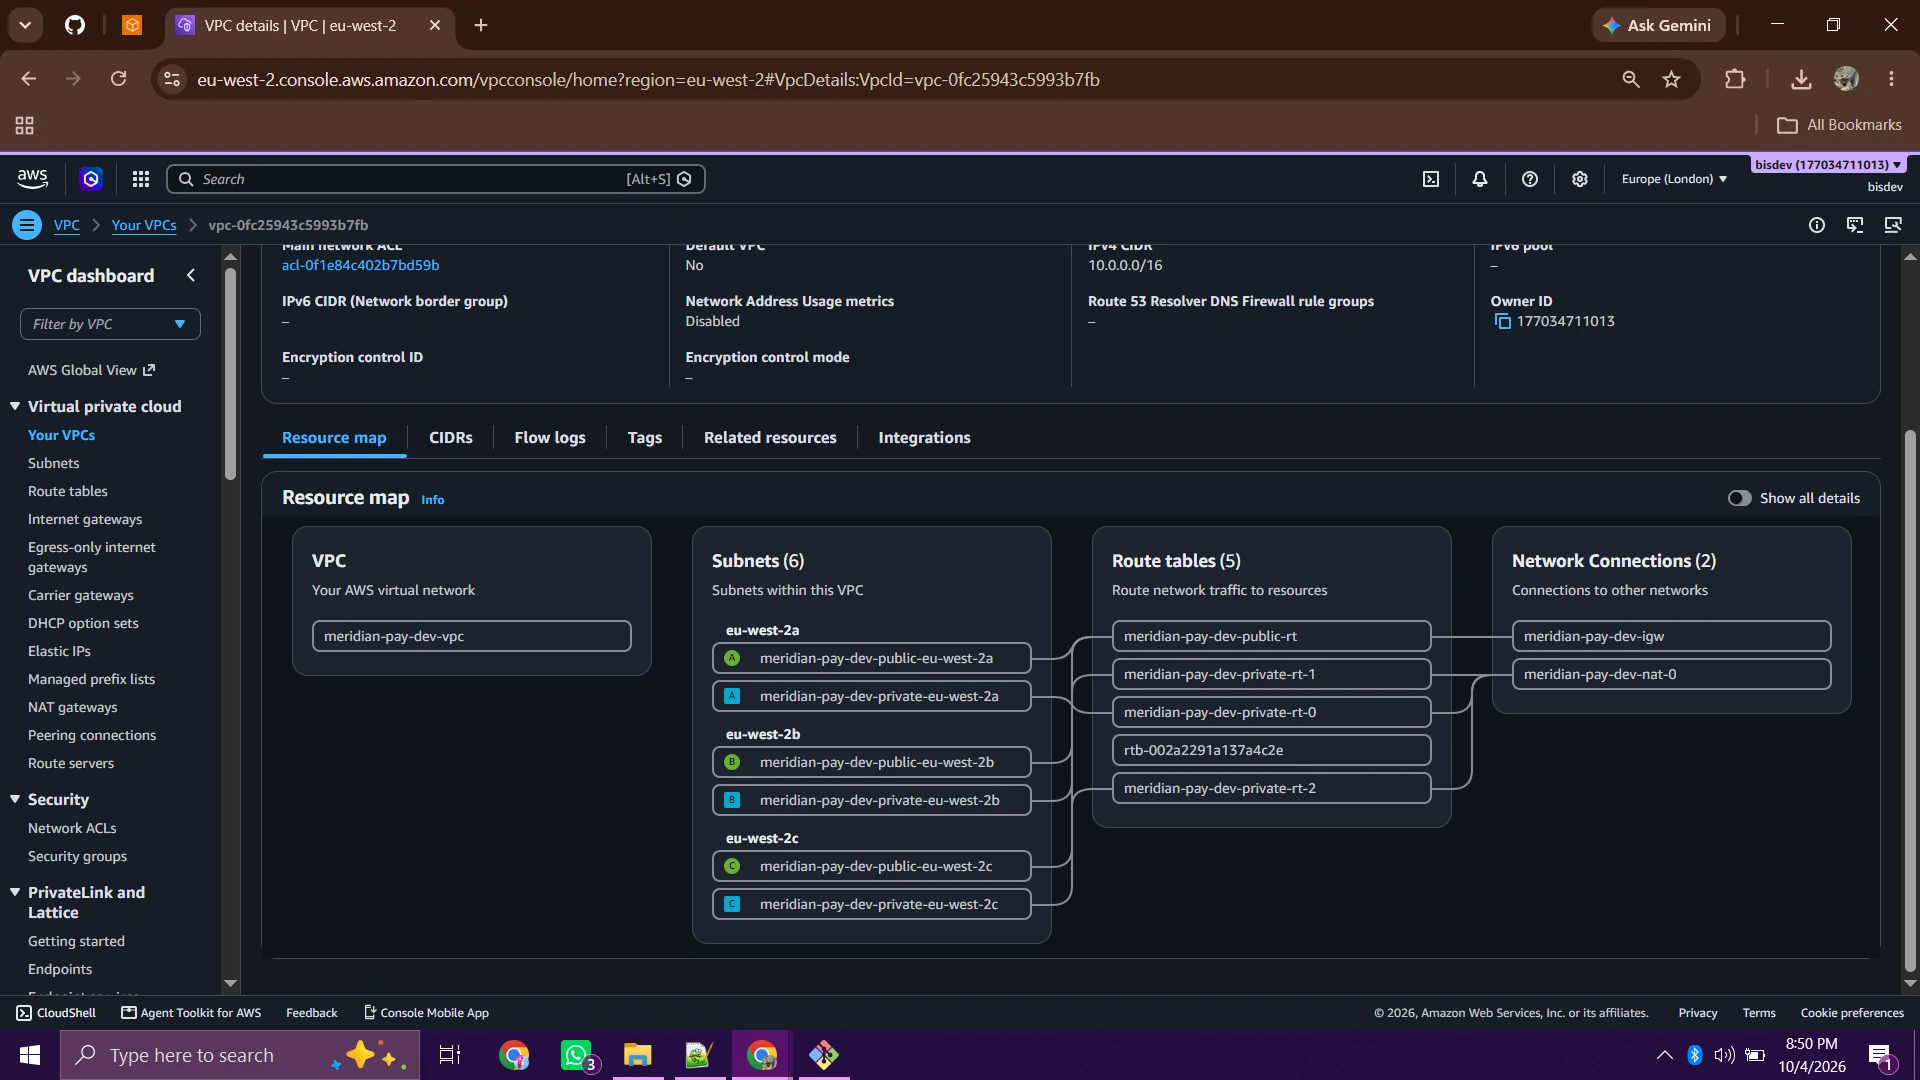
AWS VPC resource map for Meridian Pay across three availability zones
FinTech platformCloud & infraDevSecOps

Payments infrastructure built for payday morning, a partner bank outage, and a bad release

Eight services across three trust zones, Terraform-defined infrastructure, GitOps delivery and evidence that the money zone rejects what it should.

8 services7 databases3 isolated zones
AWS · EKS · Terraform · ArgoCD · GitHub ActionsFull case study ↗
Have a similar challenge?

Bring the system, the symptoms and the stakes.

I’ll help you separate the visible problem from the underlying production risk.

How I evaluate a project
01Business impact
02Production risk
03Ownership after delivery